Who Just Posted the Problem You Solve
Watches five Reddit forums and flags the strangers describing the exact problem your offer fixes
The Problem
If you sell something that solves a specific problem, your best prospect is the person describing that problem in public, right now, in their own words. Reddit is full of those people. Finding them means scrolling five forums several times a day, reading past the memes and the news threads, and deciding in the moment whether a reply would land or read as a pitch. Nobody keeps that up for more than a week.
What It Does
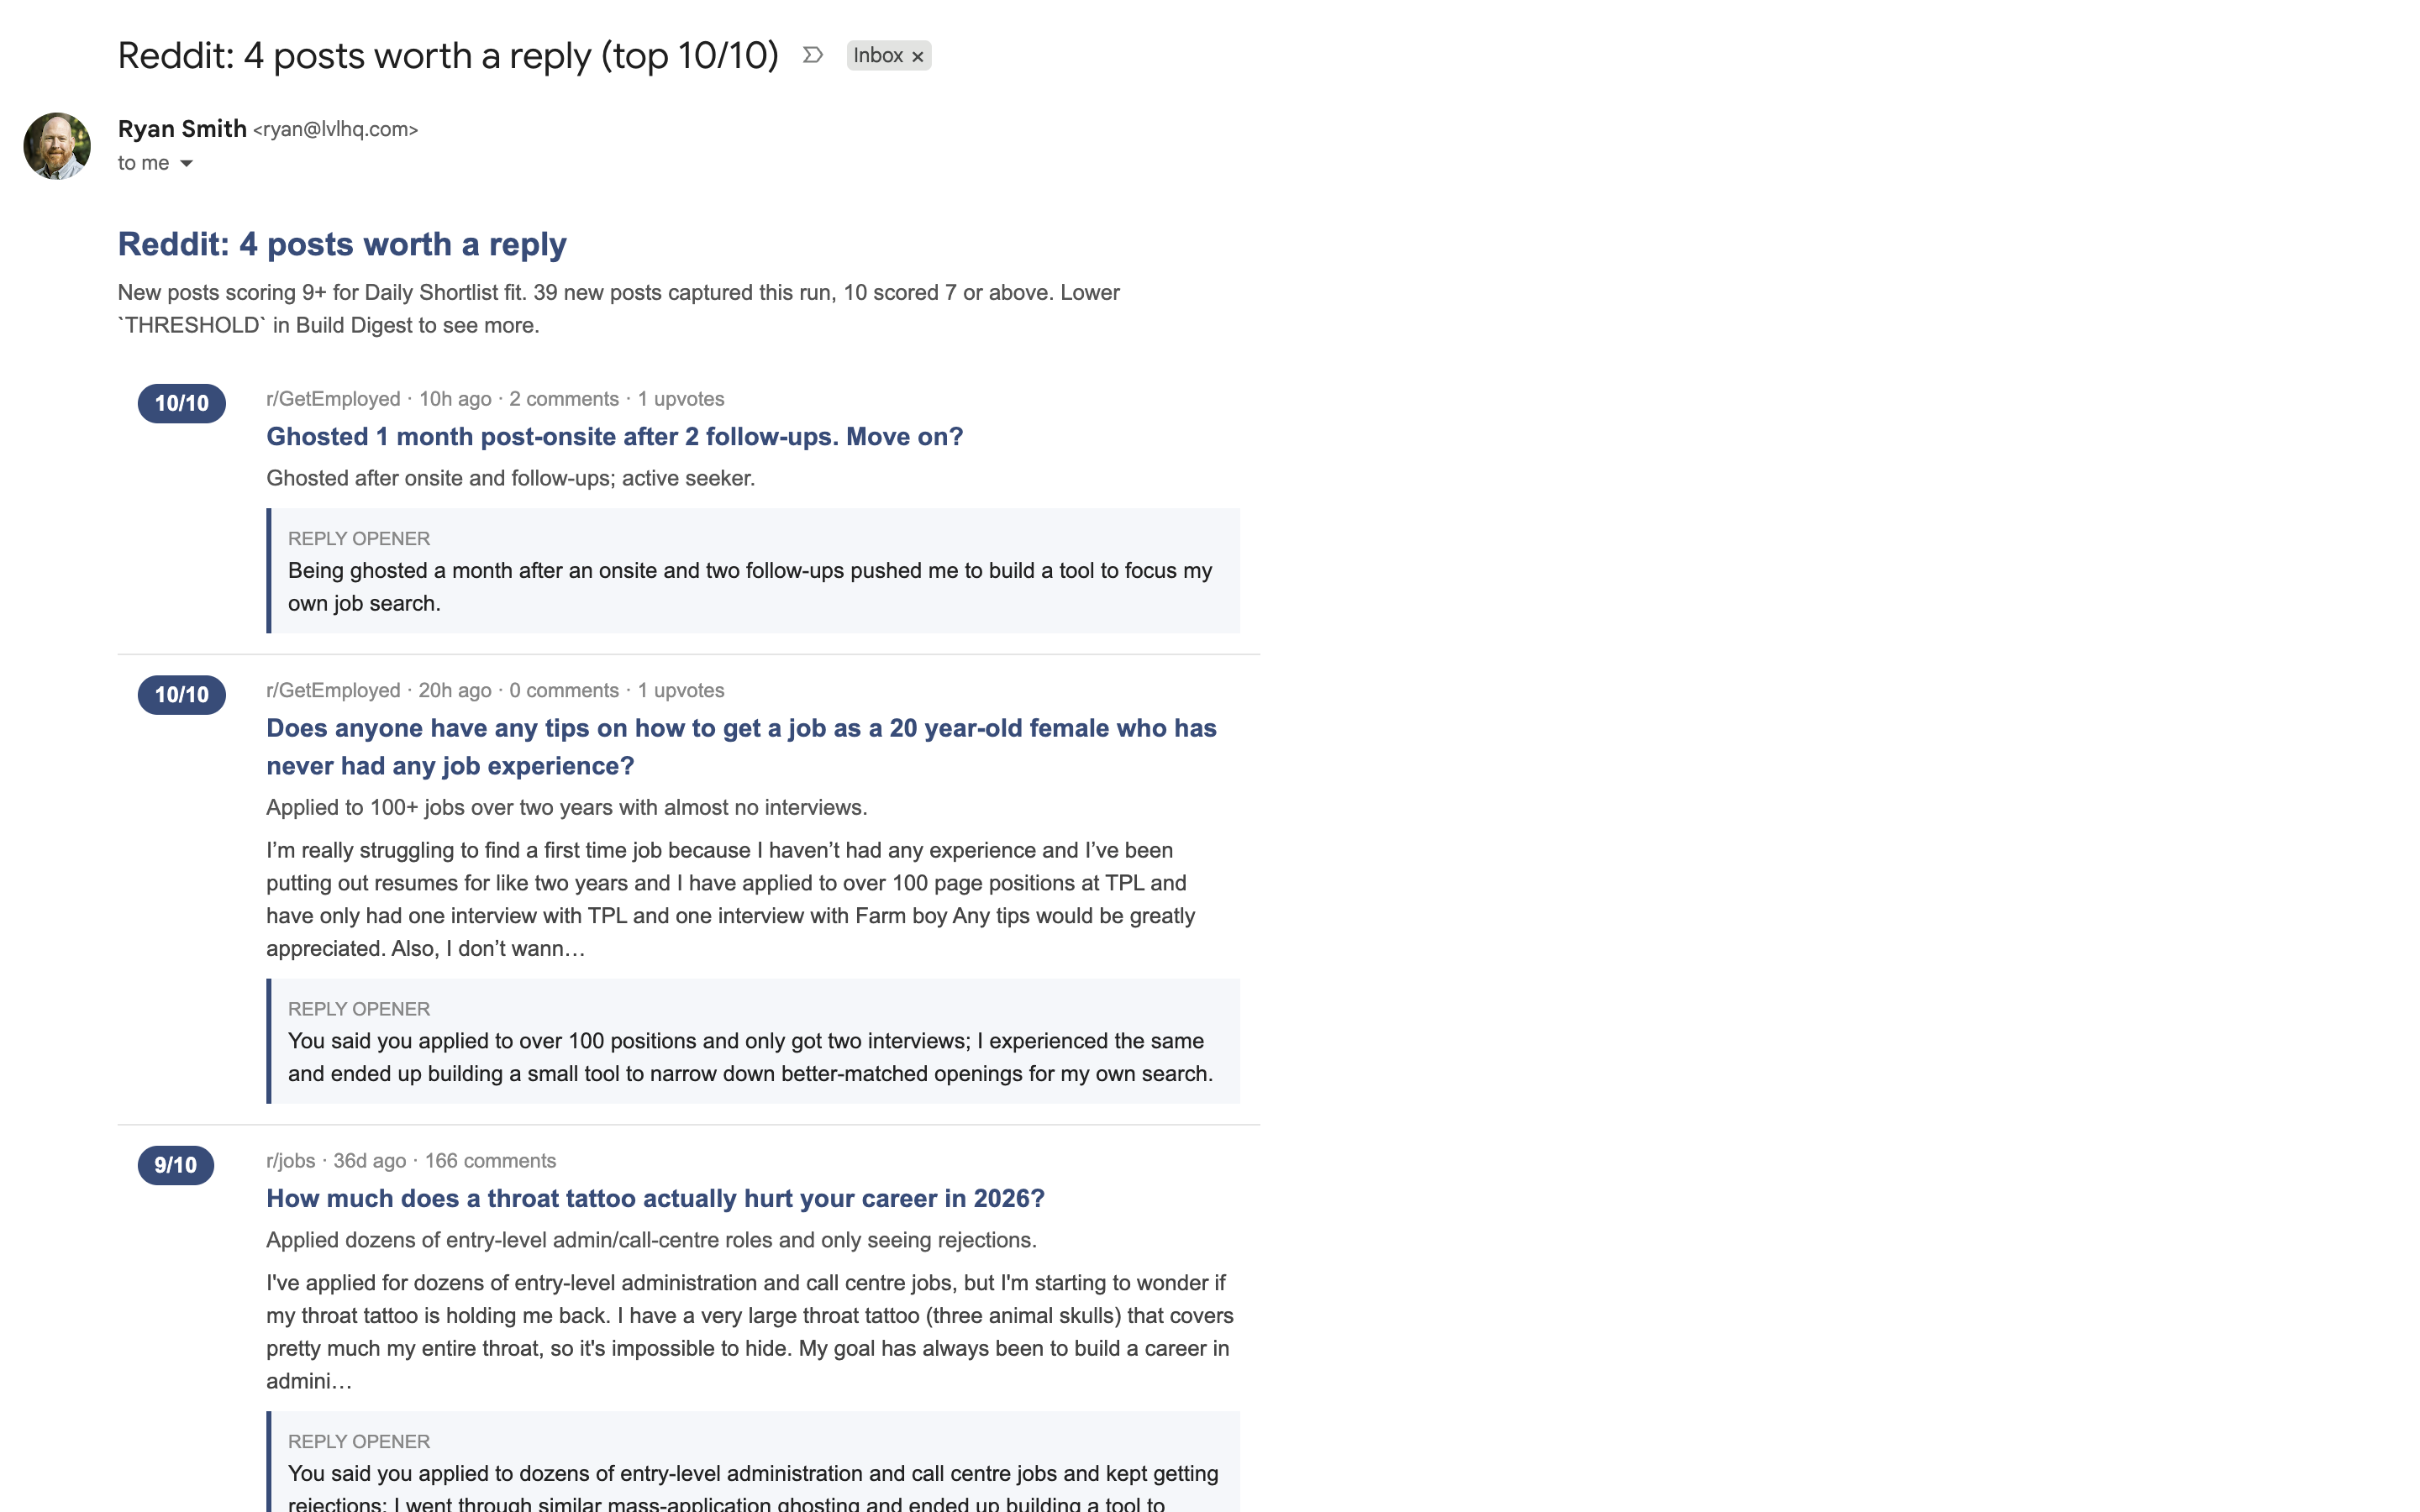
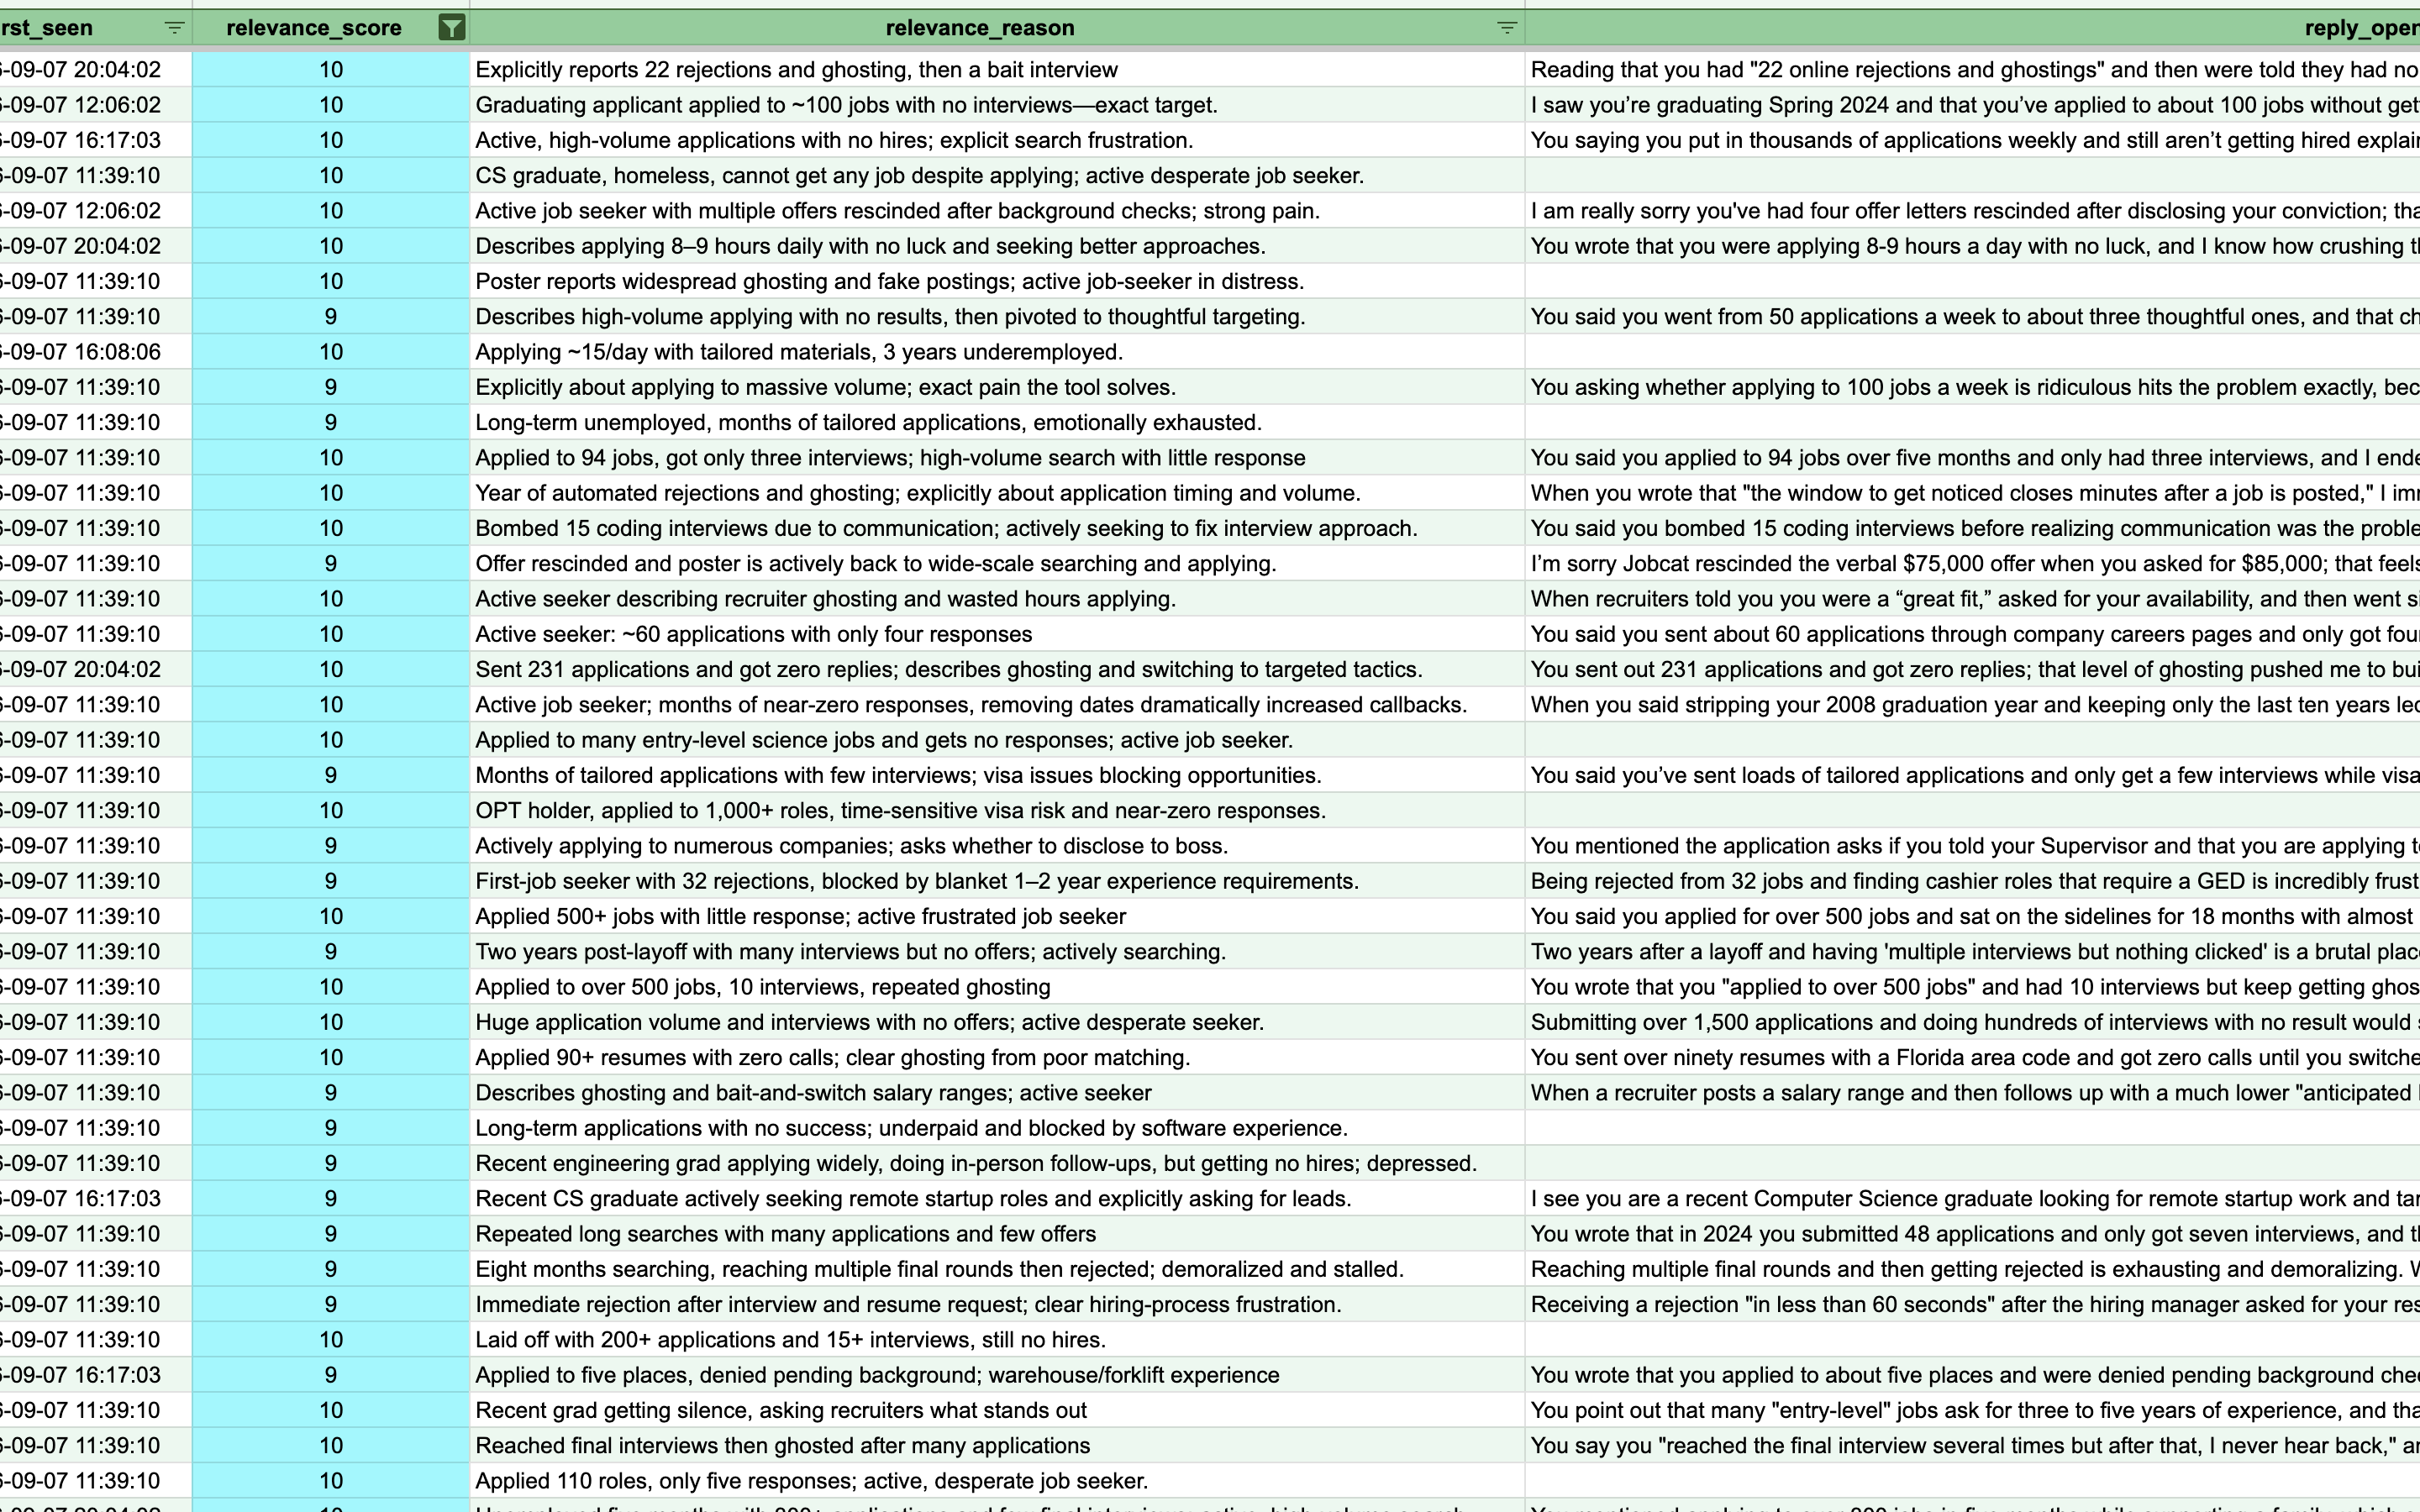
Four times a day it pulls the newest posts from five job-search forums. It throws out anything already seen, then reads each remaining post and scores it 0 to 10 against one question: is this person living the exact pain the offer fixes. Every post and score lands in a running sheet. For anything scoring 7 or higher it also drafts an opening line that quotes a specific detail from that post, written to sound like a peer rather than a vendor. Posts at 9 or above arrive as a short email digest with the opener sitting under each one.
Anyone with a real solution to a specific problem who needs to find the people already describing that problem out loud. Built here around a job-search tool, but the shape does not care what the offer is.
Outcome
758 posts were captured and scored across three days. 193 cleared 7 and 95 cleared 9, so roughly one post in eight was worth a reply, and 168 arrived with a drafted opener. No replies were ever sent. This was built to prove the targeting works, not to run a campaign.
Screenshots
How It's Built
A config node stamps the run as daily or backfill. A code node builds one scraper job per forum and hands them to a batch loop that runs them strictly one at a time, because the scraper's post limit turned out to be a global cap rather than a per-forum one. Each job calls an Apify Reddit actor and returns raw records. A normalize node flattens them into fourteen clean fields, using fallback key lists so a renamed field produces a blank column instead of a crash, and discards anything from a forum not on the target list. The sheet is read and every post ID already present is filtered out. What survives is batched eight at a time into an OpenAI call carrying the full scoring rubric, which returns a score, a fifteen-word reason and a reply opener per post. Scores are joined back onto the posts, all of it is appended to the sheet, and a digest node filters to 9 and above, sorts by score then comment count, and builds the email. An IF node stops the run when nothing cleared the bar, so an empty digest never sends.
By the numbers
- posts captured and scored
- 758
- new posts per full day
- 152 across four cycles
- posts scoring 7 or above
- 193 (25%)
- posts scoring 9 or above
- 95 (13%)
- reply openers drafted
- 168
- best forum by hit rate
- GetEmployed, 39% scored 7 or above
- worst forum by hit rate
- careerguidance, 4% scored 7 or above, dropped on day one
- scheduled run duration
- 3m14s to 4m39s per cycle
- scraping cost
- about $0.48 a day, roughly $14 a month
- scoring cost
- about $2 a day in OpenAI usage
- replies posted
- none, no outreach was attempted
Key Decisions
Pick the five forums from research, not from guessing
Ryan had already spent real time researching people who cannot find work, and the same five communities kept turning up as the source of that material. The forum list is the output of that research rather than a keyword search.
Score with a rubric that names the disqualifiers, not just the ideal
Half the value is in the caps. Offer announcements cap at 4 because the pain is over. Fresh layoff posts with no searching described yet cap at 5 because the person is not in market. Empty bodies with ambiguous titles cap at 5 rather than being guessed at.
Let the model refuse to write an opener, and make that override the score
A post can be a perfect 10 and still be one a stranger should not reply to. Disability, eviction, grief, or a poster who is a minor all force a blank opener. A missing opener costs nothing and a tone-deaf one costs the account.
Ban stock phrases in the opener prompt by name
Every opener has to be built differently and quote a detail from that specific post. The prompt forbids reusing a sentence or a closing line, and forbids pitching, naming a product, quoting a price, or dropping a link.
Raise the email threshold from 7 to 9 after seeing real volume
7 produced about 22 posts a day, which was far more than Ryan wanted to act on. The account was also brand new to those forums, and going from zero comments to nine in the first twelve hours is how a new account gets flagged. The threshold is a pace control as much as a quality filter.
Email at 9 but score and store everything
The threshold is a display setting, not a filter on the data. The sheet keeps every post at every score, so the rubric can be retuned later against real history instead of guesses.
Build a re-score path that costs no scraping money
The rubric was always going to change. Re-scoring reads the existing rows, runs the current prompt, and writes the three scoring columns back matched on post ID, so tuning costs cents instead of a fresh scrape.
Ignore upvotes entirely and sort by comment count
Reddit fuzzes vote counts for logged-out scraping, so upvotes come back as 0 and cannot be trusted. Comment count is accurate.
Scrape through Apify rather than calling Reddit directly
Reddit blocks direct calls from the n8n host. Two actors are wired in behind a single switch so one can be swapped for the other without touching the rest of the flow.
What broke & how it was fixed
The first version sent all five forums to the scraper in one job with a limit of 20 posts. The limit turned out to be a global cap across all forums rather than a per-forum one, so the run came back with 20 posts from the first forum and nothing from the other four. The fix was fanning out to one job per forum through the batch loop, which also keeps each run under the scraper's five-minute synchronous timeout. Separately, careerguidance was cut from the forum list on day one after 3 of its 79 posts scored 7 or above.
Where else this applies
Any business whose buyer describes their problem in public can run this shape. Swap the forums and rewrite the rubric and it becomes a contractor watching local groups for water damage posts, an attorney watching for probate confusion, a bookkeeper watching small business forums at tax time. The transferable part is not the scraping. It is the rubric that knows who to skip, and the rule that lets the drafting step stay silent when a reply would be the wrong move.